
Creating a new plugin: 18

What's happening with PDBLoader
Anyone reading this will know that for some months I've been working on a plugin to load a Protein Data Bank file and create a model from it. I had thought it would be available by now, but this hasn't happened.
The reasons are that, on testing a variety of PDB files to make sure it worked with any file, I found some where it did not. This needed a lot of thinking about and in the end quite a bit of reworking. This is what has taken the time.
An example
Just as an example, I found a file - actually a transfer RNA, so a nucelotide chain rather than an amino acid - where the chain also contained heterogen atoms (hetatoms), not separate from the main chain but part of it and linked to other hetatoms or nucleotides in the chain. To be clear, the chain consisted mostly of nucleotides but with occasional non-nucleotide molecules forming part of the polymer chain itself.
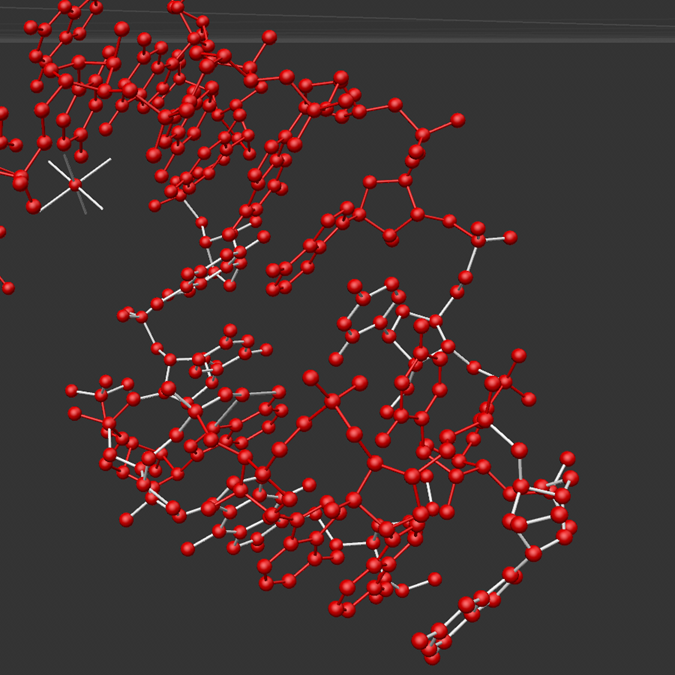
This caused two different problems. In the first case, if I wanted to colour all molecules in the chain the same colour, so that the entire chain, both atoms and bonds, were all that colour, it didn't work and the default atom and bond colours were used. This was because I had worked on the assumption that hetatoms were never part of a chain, so would never require a chain colour. Since that proved to be incorrect, the hetatoms and their bonds needed to be coloured as for the rest of the chain. For the atoms this was easy, but for the bonds it has proved extremely tricky and I haven't quite fixed it yet - though I have an idea how to do so. This image shows part of a chain which is coloured red. You can see that while all the atoms and most bonds are red, some of the bonds are white (the default bond colour), because they are bonds within hetatom molecules even though they are part of the chain:
This leads to another problem, however. It turns out that in a PDB file with hetatoms not linked as part of the chain but separate atoms or molecules, they can have the same chain identifier as the actual polymer chain. The usual reason for this is that the hetatoms are spatially associated with the actual polymer chain. A good example is haemoglobin, where there are four amino acid chains and where each chain also has a group of haem molecules. These are heterogens and not part of the polymer, but it does make sense to give them the same chain identifier. In other cases, groups of water molecules may have the same chain identifier as a polymer chain. Is it reasonable therefore to give these associated but separate molecules the same colour as the actual polymer chain? I think it is, as long as they aren't spuriously linked to the main polymer, but it does make it harder to see the hetatms when colouring chains.
The second issue was the ribbon display. To create a ribbon, a spline is created between the alpha carbons of amino acid molecules or the C1 prime atoms of nucleotides. This works well, but what if there are heterogen molecules as part of the chain? They won't have these named atoms, so should we ignore them (which in practice doesn't make much difference to the ribbon if there is only the occasional het molecule) or should they be included - maybe by using the geometric centre of the molecule? I still haven't decided on this one.
I have no doubt that other anomalies will surface.
Progress is being made
So you can see there are issues arising from the fact that biology isn't as neat and linear as we might like it to be. While accepting that there are always going to be files that just don't display correctly, and that sometimes this is due to an error in the PDB file itself, we do need to cover as many 'anomalies' as possible to avoid too many failures. Hopefully we'll get there soon.
Page last updated September 21st 2026